Artificial Intelligence
Making machines smarter for improved safety, efficiency and comfort.
Our AI research encompasses advances in computer vision, speech and audio processing, as well as data analytics. Key research themes include improved perception based on machine learning techniques, learning control policies through model-based reinforcement learning, as well as cognition and reasoning based on learned semantic representations. We apply our work to a broad range of automotive and robotics applications, as well as building and home systems.
Quick Links
-
Researchers
Jonathan
Le Roux
Toshiaki
Koike-Akino
Gordon
Wichern
Ye
Wang
Anoop
Cherian
Chiori
Hori
Tim K.
Marks
Michael J.
Jones
Jing
Liu
Yoshiki
Masuyama
Kieran
Parsons
Suhas
Lohit
Daniel N.
Nikovski
Kuan-Chuan
Peng
Matthew
Brand
Moitreya
Chatterjee
Pu
(Perry)
Wang
Philip V.
Orlik
Christoph
Boeddeker
Siddarth
Jain
Hassan
Mansour
Petros T.
Boufounos
Julius
Richter
Radu
Corcodel
Pedro
Miraldo
William S.
Yerazunis
Yebin
Wang
Jianlin
Guo
Arvind
Raghunathan
Hongbo
Sun
Ankush
Chakrabarty
Stefano
Di Cairano
Chungwei
Lin
Yanting
Ma
Saviz
Mowlavi
Bingnan
Wang
Christopher R.
Laughman
Lalit
Manam
Alexander
Schperberg
Kei
Suzuki
Anthony
Vetro
Jinyun
Zhang
Vedang M.
Deshpande
Dehong
Liu
Abraham P.
Vinod
Kenji
Inomata
-
Awards
-
AWARD MERL Team Wins Real-TSE Challenge Track 2 on Offline Target Speaker Extraction Date: July 6, 2026
Awarded to: Dominik Klement, Yoshiki Masuyama, Christoph Boeddeker, Kohei Saijo, Julius Richter, Gordon Wichern, and Jonathan Le Roux
MERL Contacts: Christoph Boeddeker; Jonathan Le Roux; Yoshiki Masuyama; Julius Richter; Gordon Wichern
Research Areas: Artificial Intelligence, Machine Learning, Speech & AudioBriefMERL's Speech & Audio team, led by MERL intern Dominik Klement, ranked 1st out of 11 teams in Track 2, "Offline Target Speaker Extraction," of the Real-TSE Challenge. The challenge focuses on target speaker extraction (TSE) from real-world conversational recordings in either English or Chinese, where the goal is to extract the speech of a target speaker in the presence of interfering speakers, background noise, and reverberation.
While modern TSE systems have achieved strong performance on simulated speech mixtures, their performance can degrade considerably on real-world recordings due to the mismatch between simulated training data and actual conversational environments. The Real-TSE Challenge was designed to advance TSE under these realistic conditions, using real far-field conversational recordings for evaluation.
The MERL team won Track 2 by focusing on training data and curriculum learning rather than introducing a new model architecture. Starting from a strong speech separation model, the team progressively trained the system on fully overlapping synthetic speech, simulated conversations, realistic far-field mixtures, and finally real conversational recordings. This approach reduced the token error rate (TER), measured at either the word (English) or character (Chinese) level, from 70% to 37% on the development set and achieved a final TER of 61.3% on the evaluation set, best among the 11 participating teams. The team also topped the leaderboard in terms of the aggregate ranking across the four measures evaluating intelligibility, target speaker presence rate, speaker similarity, and perceptual quality.
The team also investigated the reliability of the challenge metrics and demonstrated that neural network-based speaker similarity and predicted speech-quality scores could be substantially improved without a corresponding improvement in perceptual quality. Because learned metrics can be susceptible to adversarial attacks or optimization that exploits weaknesses in the metric itself, these findings highlight both the importance of realistic training data for real-world TSE and the need for robust evaluation metrics when developing speech extraction systems.
A paper summarizing the team's findings will be presented at the IEEE Spoken Language Technology (SLT) 2026 workshop, to be held in Palermo, Italy from December 13-16, 2026.
REAL-TSE Challenge: Track 2 rankings — Offline Target Speaker Extraction Rank Team TER ↓ F1 ↑ SIM ↑ P808 ↑ Score ↓ 1 MERL 0.613 (1) 0.861 (2) 0.538 (3) 3.371 (2) 2.00 2 YiJiaHe 0.639 (2) 0.871 (1) 0.565 (1) 3.128 (9) 3.25 3 CARTSE 0.651 (3) 0.857 (4) 0.544 (2) 3.138 (8) 4.25 4 WasedaM 0.675 (5) 0.858 (3) 0.480 (6) 3.232 (6) 5.00 5 SonicAGI 0.680 (6) 0.851 (6) 0.471 (7) 3.258 (5) 6.00 6 WAKA 0.670 (4) 0.847 (8) 0.471 (7) 3.150 (7) 6.50 6 SHNU-TSE 0.731 (9) 0.840 (9) 0.507 (5) 3.362 (3) 6.50 7 ChuEst 0.710 (7) 0.831 (11) 0.532 (4) 3.064 (10) 8.00 8 pyannoteAI 0.728 (8) 0.855 (5) 0.464 (9) 2.904 (12) 8.50 9 AGH-JHU 0.743 (10) 0.837 (10) 0.434 (11) 3.335 (4) 8.75 10 WHU_IASP 0.757 (11) 0.850 (7) 0.465 (8) 2.961 (11) 9.25 11 CUDA_OUT_OF_MEMORY 0.827 (12) 0.819 (13) 0.364 (13) 3.435 (1) 9.75 12 BSRNN_EMB Baseline 0.829 (13) 0.829 (12) 0.417 (12) 2.875 (13) 12.50 12 BSRNN_TFMAP Baseline 0.838 (14) 0.829 (12) 0.443 (10) 2.756 (14) 12.50 ↓ Lower is better; ↑ higher is better. Parentheses show metric ranks. The score is the average of the four dense metric ranks; tied scores share a position. Best metric values are bold. P808 denotes DNSMOS-P808.
Source: Official REAL-TSE Challenge rankings. BSRNN entries are organizer baselines.
-
AWARD MERL Team Wins DCASE 2026 Challenge on Anomalous Sound Detection for Machine Condition Monitoring Date: June 30, 2026
Awarded to: Takuya Fujimura, Gordon Wichern, Yoshiki Masuyama, Christoph Boeddeker, Kohei Saijo, Julius Richter, Takahiro Edo, and Jonathan Le Roux
MERL Contacts: Christoph Boeddeker; Jonathan Le Roux; Yoshiki Masuyama; Julius Richter; Gordon Wichern
Research Areas: Artificial Intelligence, Machine Learning, Signal Processing, Speech & AudioBrief- MERL's Speech & Audio team ranked 1st out of 51 teams in the DCASE 2026 Challenge’s Task 2, “Noise-aware Unsupervised Anomalous Sound Detection for Machine Condition Monitoring.” The team was led by MERL intern Takuya Fujimura, and also included Gordon Wichern, Yoshiki Masuyama, Christoph Boeddeker, Kohei Saijo, Julius Richter, Takahiro Edo, and Jonathan Le Roux.
The IEEE AASP Challenge on Detection and Classification of Acoustic Scenes and Events (DCASE Challenge), started in 2013, has been organized yearly since 2016, and gathers challenges on multiple tasks related to the detection, analysis, and generation of sound events. This year, the DCASE 2026 Challenge received 421 submissions from 135 teams across seven tasks.
The MERL team won Task 2, Noise-aware Unsupervised Anomalous Sound Detection for Machine Condition Monitoring, which aims at building noise-robust systems for automatically detecting machine failure via microphones when only normal machine operating data is available for system development. Task 2 was by far the most popular out of the 7 DCASE 2026 tasks, with 51 teams submitting 168 entries. The MERL team's system was built around MERL’s recently proposed paradigm of noise-aware self-supervised learning, which extracts noise robust features leveraging two-channel recordings, in which one microphone is used to capture noise. Anomaly detection is then performed in the extracted denoised feature space using advanced score normalization. The team's best submission obtained a composite score of 70.24% on five evaluation machines, largely outperforming the 2nd best team's 65.45%.
MERL also participated in Task 4, Spatial Semantic Segmentation of Sound Scenes (S5) and placed 3rd out of 10 teams in separation performance. Our cascaded system consists of universal sound separation with source counting, source classification, and class-aware refinement, where the separation and refinement modules are built upon MERL's TF-Locoformer separation technology. Notably, the team's best submission obtained a label prediction accuracy of 76.92% on the evaluation set, largely outperforming the 2nd best team's 65.54%.
- MERL's Speech & Audio team ranked 1st out of 51 teams in the DCASE 2026 Challenge’s Task 2, “Noise-aware Unsupervised Anomalous Sound Detection for Machine Condition Monitoring.” The team was led by MERL intern Takuya Fujimura, and also included Gordon Wichern, Yoshiki Masuyama, Christoph Boeddeker, Kohei Saijo, Julius Richter, Takahiro Edo, and Jonathan Le Roux.
-
AWARD MERL team wins the Generative Data Augmentation of Room Acoustics (GenDARA) 2025 Challenge Date: April 7, 2025
Awarded to: Christopher Ick, Gordon Wichern, Yoshiki Masuyama, François G. Germain, and Jonathan Le Roux
MERL Contacts: Jonathan Le Roux; Yoshiki Masuyama; Gordon Wichern
Research Areas: Artificial Intelligence, Machine Learning, Speech & AudioBrief- MERL's Speech & Audio team ranked 1st out of 3 teams in the Generative Data Augmentation of Room Acoustics (GenDARA) 2025 Challenge, which focused on “generating room impulse responses (RIRs) to supplement a small set of measured examples and using the augmented data to train speaker distance estimation (SDE) models". The team was led by MERL intern Christopher Ick, and also included Gordon Wichern, Yoshiki Masuyama, François G. Germain, and Jonathan Le Roux.
The GenDARA Challenge was organized as part of the Generative Data Augmentation (GenDA) workshop at the 2025 IEEE International Conference on Acoustics, Speech, and Signal Processing (ICASSP 2025), and held on April 7, 2025 in Hyderabad, India. Yoshiki Masuyama presented the team's method, "Data Augmentation Using Neural Acoustic Fields With Retrieval-Augmented Pre-training".
The GenDARA challenge aims to promote the use of generative AI to synthesize RIRs from limited room data, as collecting or simulating RIR datasets at scale remains a significant challenge due to high costs and trade-offs between accuracy and computational efficiency. The challenge asked participants to first develop RIR generation systems capable of expanding a sparse set of labeled room impulse responses by generating RIRs at new source–receiver positions. They were then tasked with using this augmented dataset to train speaker distance estimation systems. Ranking was determined by the overall performance on the downstream SDE task. MERL’s approach to the GenDARA challenge centered on a geometry-aware neural acoustic field model that was first pre-trained on a large external RIR dataset to learn generalizable mappings from 3D room geometry to room impulse responses. For each challenge room, the model was then adapted or fine-tuned using the small number of provided RIRs, enabling high-fidelity generation of RIRs at unseen source–receiver locations. These augmented RIR sets were subsequently used to train the SDE system, improving speaker distance estimation by providing richer and more diverse acoustic training data.
- MERL's Speech & Audio team ranked 1st out of 3 teams in the Generative Data Augmentation of Room Acoustics (GenDARA) 2025 Challenge, which focused on “generating room impulse responses (RIRs) to supplement a small set of measured examples and using the augmented data to train speaker distance estimation (SDE) models". The team was led by MERL intern Christopher Ick, and also included Gordon Wichern, Yoshiki Masuyama, François G. Germain, and Jonathan Le Roux.
See All Awards for Artificial Intelligence -
-
News & Events
-
TALK [MERL Seminar Series 2026] Tess Smidt presents talk titled Adventures in Building Structure into Models: Lessons from Constructing Euclidean Neural Networks for Physics Date & Time: Wednesday, August 19, 2026; 11:00 AM
Speaker: Tess Smidt, MIT
MERL Host: Suhas Lohit
Research Areas: Artificial Intelligence, Machine LearningAbstract Symmetry provides a powerful lens for building machine learning models that interact with scientific data. Euclidean neural networks (E(3)NNs) make this concrete: architectures that encode transformation laws through group representations, enabling models to operate on geometric and tensorial data while respecting the structure of physical systems. In this talk, I’ll share lessons from building and applying these models in practice. Incorporating symmetry shapes how data is represented, how models learn, and how they are optimized, while introducing new trade-offs in expressivity and computation.
-
NEWS MERL Presents Five Papers at IEEE Quantum Week 2026 Date: September 13, 2026 - September 18, 2026
Where: Toronto, Canada
MERL Contact: Toshiaki Koike-Akino
Research Areas: Applied Physics, Artificial Intelligence, Machine Learning, Optimization, Signal ProcessingBrief- MERL is pleased to announce that five papers have been accepted to the 2026 IEEE International Conference on Quantum Computing and Engineering (QCE), also known as IEEE Quantum Week 2026, held September 13–18, 2026, in Toronto, Canada.
The papers highlight MERL’s recent advances in quantum computing, spanning hardware-efficient quantum state preparation, quantum low-density parity-check (QLDPC) code design, graph-cover-based code construction, machine-learning-assisted code search, and reinforcement-learning-guided quantum error correction. Together, these works address important challenges toward more efficient and reliable quantum computing systems.
The five papers are:
- “Near-Lower-Bound Approximate Quantum State Preparation with Hardware-Efficient Circuits” — Toshiaki Koike-Akino (TR2026-131)
- “Reinforcement-Learning-Guided Multi-Branch Decoding of Quantum LDPC Codes” — Vahid Nourozi, Toshiaki Koike-Akino, and David Mitchell (TR2026-130)
- “Q-Learning Base Search Voltage-Labeled Covers for Weight-Six Bivariate-Bicycle Quantum LDPC Codes” — Vahid Nourozi, David Mitchell, and Toshiaki Koike-Akino (TR2026-132)
- “Collision-Voltage Design of Directional Covers for Bivariate Bicycle Quantum LDPC Codes” — Vahid Nourozi, David Mitchell, and Toshiaki Koike-Akino (TR2026-133)
- “Base-Preserving APM/Voltage Lifts of Bivariate Bicycle Quantum LDPC Codes” — Vahid Nourozi, David Mitchell, and Toshiaki Koike-Akino (TR2026-129)
- MERL is pleased to announce that five papers have been accepted to the 2026 IEEE International Conference on Quantum Computing and Engineering (QCE), also known as IEEE Quantum Week 2026, held September 13–18, 2026, in Toronto, Canada.
See All News & Events for Artificial Intelligence -
-
Research Highlights
-
ReCoVLA: VLM-Guided Reward Compilation for Failure Recovery in Vision-Language-Action Policies -
LLawCo: Learning Laws of Cooperation for Modeling Embodied Multi-Agent Behavior -
Point4Cast: Streaming Dynamic Scene Reconstruction and Forecasting -
AssemblyBench: Physics-Aware Assembly of Complex Industrial Objects -
SLAM-MER: Revisiting Monocular SLAM with Spatio-Temporal Scene Modeling -
Parallel Rigidity Matters for Bundle Adjustment -
LLMPhy: Parameter-Identifiable Physical Reasoning Combining Large Language Models and Physics Engines -
BodyVLA: Embedding Morphology into Transformers for Cross-Robot Policy Learning -
PS-NeuS: A Probability-guided Sampler for Neural Implicit Surface Rendering -
Quantum AI Technology -
TI2V-Zero: Zero-Shot Image Conditioning for Text-to-Video Diffusion Models -
Gear-NeRF: Free-Viewpoint Rendering and Tracking with Motion-Aware Spatio-Temporal Sampling -
Private, Secure, and Reliable Artificial Intelligence -
Steered Diffusion -
Sustainable AI -
Robust Machine Learning -
mmWave Beam-SNR Fingerprinting (mmBSF) -
Video Anomaly Detection -
Biosignal Processing for Human-Machine Interaction -
Task-aware Unified Source Separation - Audio Examples
-
-
Internships
-
EA0234: Internship - Multi-modal sensor fusion for predictive maintenance
-
CV0101: Internship - Multimodal Algorithmic Reasoning
-
OR0313: Internship - Foundation Models for Humanoid Robots
See All Internships for Artificial Intelligence -
-
Openings
-
CI0177: Postdoctoral Research Fellow - Agentic AI
-
SA0297: Postdoctoral Research Fellow - AI for Science
See All Openings at MERL -
-
Recent Publications
- , "Echoes after Edits: Room Impulse Response Estimation for Geometry Update", Interspeech, September 2026.BibTeX TR2026-140 PDF
- @inproceedings{Bhosale2026sep2,
- author = {Bhosale, Swapnil and Masuyama, Yoshiki and Chatterjee, Moitreya and Boeddeker, Christoph and Richter, Julius and Wichern, Gordon and {Le Roux}, Jonathan},
- title = {{Echoes after Edits: Room Impulse Response Estimation for Geometry Update}},
- booktitle = {Interspeech},
- year = 2026,
- month = sep,
- url = {https://www.merl.com/publications/TR2026-140}
- }
- , "Dual-Geometry Manifolds for Few-shot RIR Prediction", Interspeech, September 2026.BibTeX TR2026-139 PDF
- @inproceedings{Bhosale2026sep,
- author = {Bhosale, Swapnil and Wichern, Gordon and Masuyama, Yoshiki and Chatterjee, Moitreya and Boeddeker, Christoph and Richter, Julius and Zhu, Xiatian and {Le Roux}, Jonathan},
- title = {{Dual-Geometry Manifolds for Few-shot RIR Prediction}},
- booktitle = {Interspeech},
- year = 2026,
- month = sep,
- url = {https://www.merl.com/publications/TR2026-139}
- }
- , "Speaker Identity as Sole Supervision for Speech Separation", Interspeech, September 2026.BibTeX TR2026-137 PDF
- @inproceedings{Boeddeker2026sep,
- author = {Boeddeker, Christoph and Masuyama, Yoshiki and Richter, Julius and Edo, Takahiro and Wichern, Gordon and {Le Roux}, Jonathan},
- title = {{Speaker Identity as Sole Supervision for Speech Separation}},
- booktitle = {Interspeech},
- year = 2026,
- month = sep,
- url = {https://www.merl.com/publications/TR2026-137}
- }
- , "Plan and Double-Check: Streaming Multimodal Q-Former for Online Robot Action Generation", Interspeech, September 2026.BibTeX TR2026-136 PDF
- @inproceedings{Hori2026sep,
- author = {{Hori, Chiori and Korekata, Ryosuke and Kambara, Motonari and Masuyama, Yoshiki and Jain, Siddarth and Corcodel, Radu and Romeres, Diego and Le Roux, Jonathan}},
- title = {{Plan and Double-Check: Streaming Multimodal Q-Former for Online Robot Action Generation}},
- booktitle = {Interspeech},
- year = 2026,
- month = sep,
- url = {https://www.merl.com/publications/TR2026-136}
- }
- , "Test-Time Attention: Can Robots Better Follow Commands?", IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS) IARL Workshop, September 2026.BibTeX TR2026-142 PDF
- @inproceedings{Liu2026sep,
- author = {Liu, Jing and Wang, Ye and Suzuki, Kei and Koike-Akino, Toshiaki},
- title = {{Test-Time Attention: Can Robots Better Follow Commands?}},
- booktitle = {IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS) IARL Workshop},
- year = 2026,
- month = sep,
- url = {https://www.merl.com/publications/TR2026-142}
- }
- , "HRTF Personalization via Sim-to-Real Neural Field", Interspeech, September 2026.BibTeX TR2026-135 PDF
- @inproceedings{Masuyama2026sep2,
- author = {Masuyama, Yoshiki and Wichern, Gordon and Boeddeker, Christoph and Richter, Julius and Edo, Takahiro and Bhosale, Swapnil and {Le Roux}, Jonathan},
- title = {{HRTF Personalization via Sim-to-Real Neural Field}},
- booktitle = {Interspeech},
- year = 2026,
- month = sep,
- url = {https://www.merl.com/publications/TR2026-135}
- }
- , "Mind the Gap: Detecting Cluster Exits for Robust Local Density-Based Score Normalization in Anomalous Sound Detection", Interspeech, September 2026.BibTeX TR2026-138 PDF
- @inproceedings{Wilkinghoff2026sep,
- author = {Wilkinghoff, Kevin and Wichern, Gordon and {Le Roux}, Jonathan and Tan, Zheng-Hua},
- title = {{Mind the Gap: Detecting Cluster Exits for Robust Local Density-Based Score Normalization in Anomalous Sound Detection}},
- booktitle = {Interspeech},
- year = 2026,
- month = sep,
- url = {https://www.merl.com/publications/TR2026-138}
- }
- , "LEAP-VLA: Latent-Enhanced Action Prototyping via Continuous Residual Latent Spaces for Vision-Language-Action Models", European Conference on Computer Vision (ECCV), September 2026.BibTeX TR2026-127 PDF
- @inproceedings{Yu2026sep,
- author = {Yu, Bo-Yun and Peng, Kuan-Chuan and Hsieh, Jun-Wei},
- title = {{LEAP-VLA: Latent-Enhanced Action Prototyping via Continuous Residual Latent Spaces for Vision-Language-Action Models}},
- booktitle = {European Conference on Computer Vision (ECCV)},
- year = 2026,
- month = sep,
- url = {https://www.merl.com/publications/TR2026-127}
- }
- , "Echoes after Edits: Room Impulse Response Estimation for Geometry Update", Interspeech, September 2026.
-
Videos
-
Software & Data Downloads
-
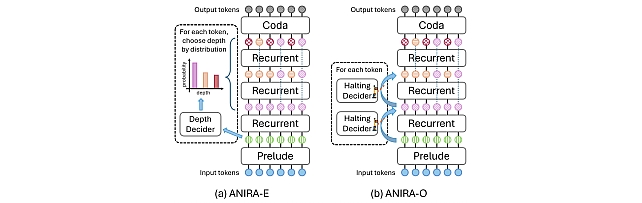
Understanding Dynamic Compute Allocation in Recurrent Transformers -
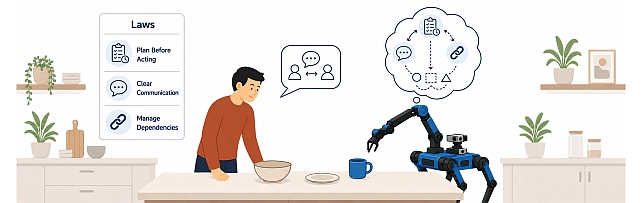
Learning Laws of Cooperation for Modeling Embodied Multi-Agent Behavior -
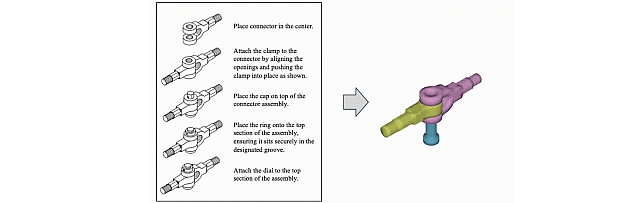
Physics-Aware Assembly of Complex Industrial Objects -
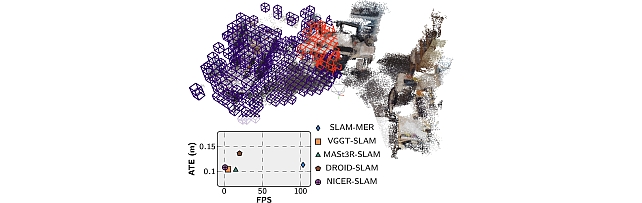
Mitsubishi Electric Research framework for visual SLAM -
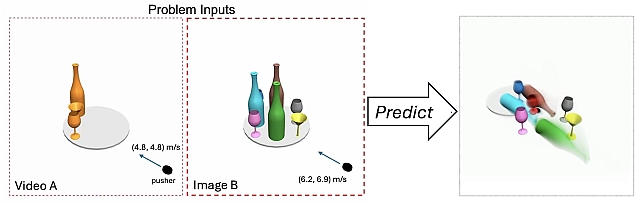
Parameter-Identifiable Physical Reasoning Combining Large Language Models and Physics Engines -
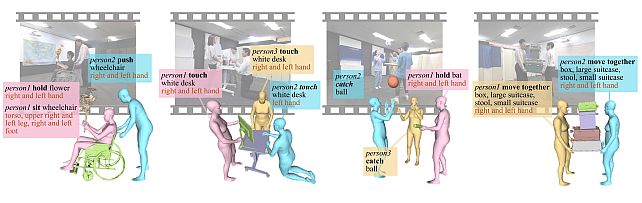
MMHOI Dataset: Modeling Complex 3D Multi-Human Multi-Object Interactions -
Embracing Cacophony -
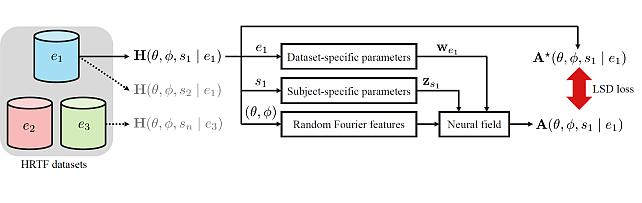
Subject- and Dataset-Aware Neural Field for HRTF Modeling -
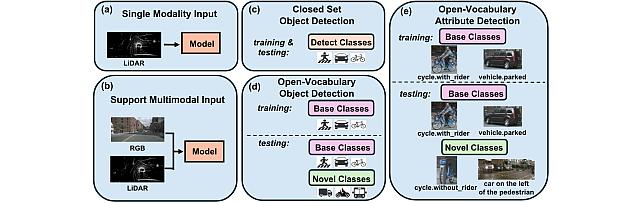
Open Vocabulary Attribute Detection Dataset -
Long-Tailed Online Anomaly Detection dataset -
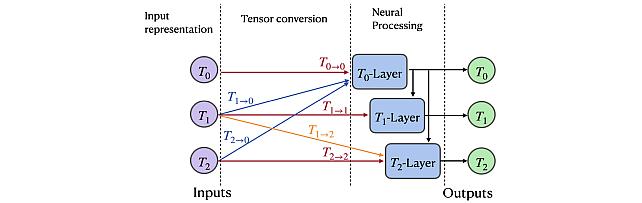
Group Representation Networks -
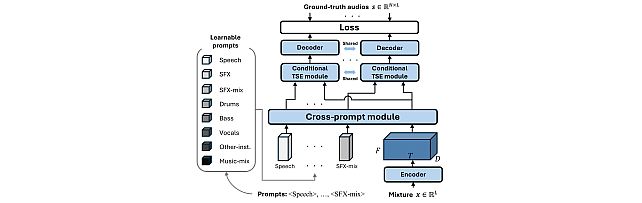
Task-Aware Unified Source Separation -
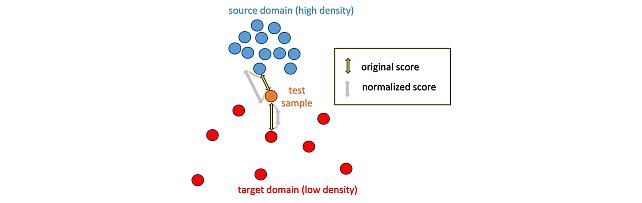
Local Density-Based Anomaly Score Normalization for Domain Generalization -
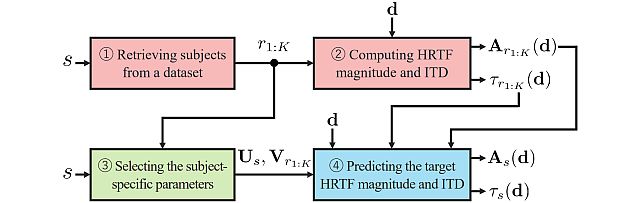
Retrieval-Augmented Neural Field for HRTF Upsampling and Personalization -
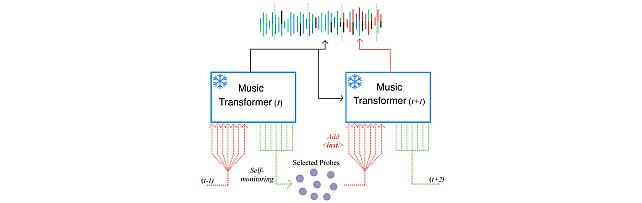
Self-Monitored Inference-Time INtervention for Generative Music Transformers -
MEL-PETs Defense for LLM Privacy Challenge -
MEL-PETs Joint-Context Attack for LLM Privacy Challenge -
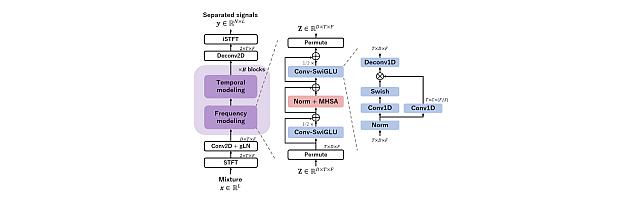
Transformer-based model with LOcal-modeling by COnvolution -
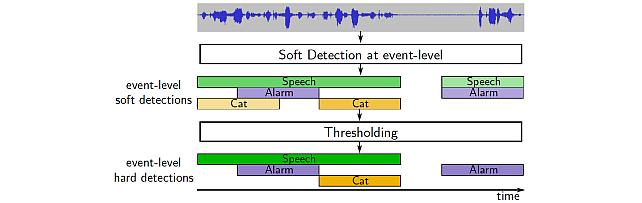
Sound Event Bounding Boxes -
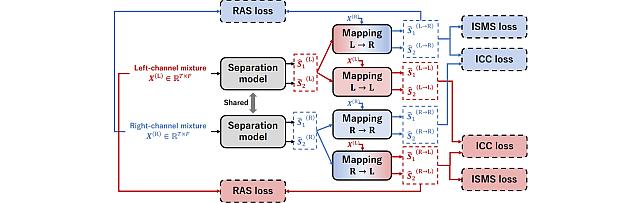
Enhanced Reverberation as Supervision -
Zero-Shot Image Conditioning for Text-to-Video Diffusion Models -
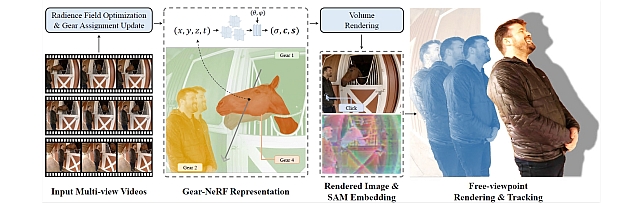
Gear Extensions of Neural Radiance Fields -
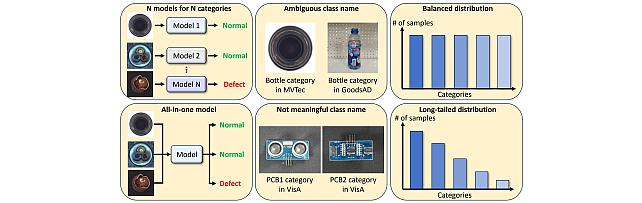
Long-Tailed Anomaly Detection Dataset -
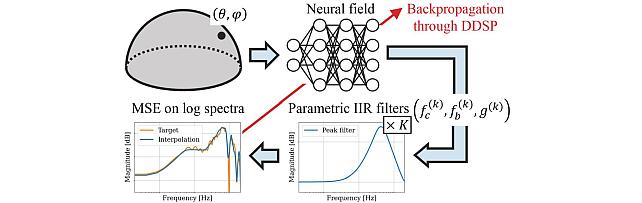
Neural IIR Filter Field for HRTF Upsampling and Personalization -
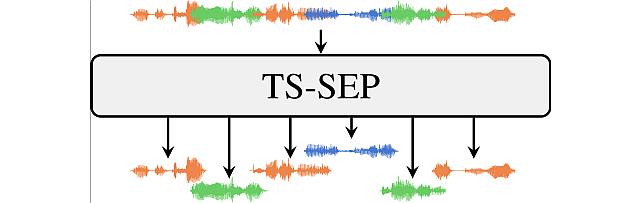
Target-Speaker SEParation -
Pixel-Grounded Prototypical Part Networks -

Steered Diffusion -
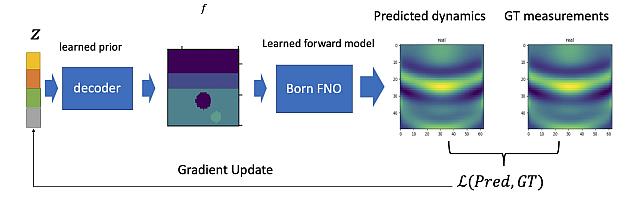
Learned Born Operator for Reflection Tomographic Imaging -
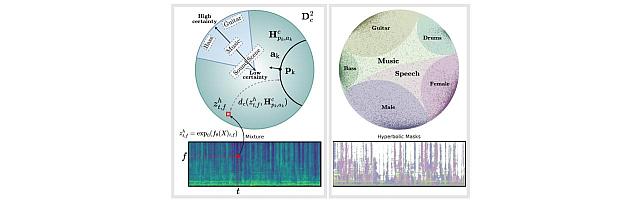
Hyperbolic Audio Source Separation -
Simple Multimodal Algorithmic Reasoning Task Dataset -
Partial Group Convolutional Neural Networks -
SOurce-free Cross-modal KnowledgE Transfer -
Audio-Visual-Language Embodied Navigation in 3D Environments -
Nonparametric Score Estimators -
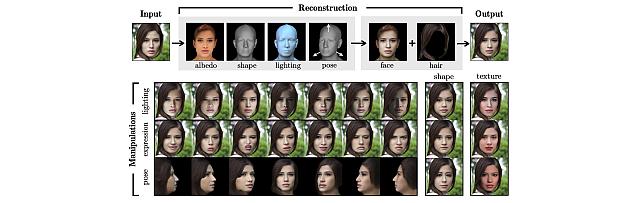
3D MOrphable STyleGAN -
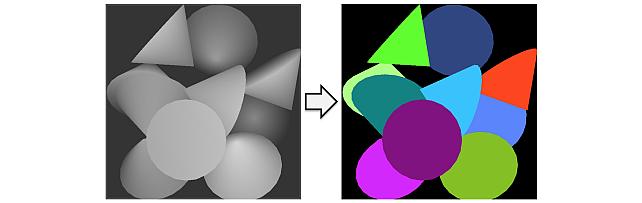
Instance Segmentation GAN -
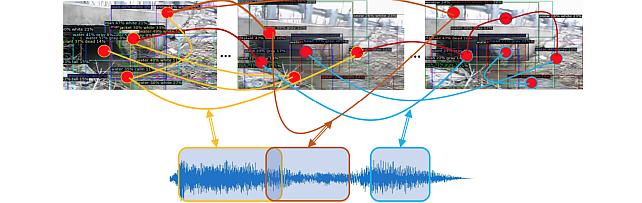
Audio Visual Scene-Graph Segmentor -
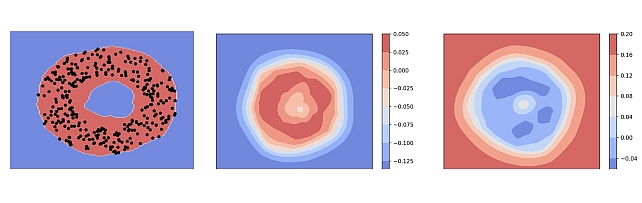
Generalized One-class Discriminative Subspaces -
Goal directed RL with Safety Constraints -
Hierarchical Musical Instrument Separation -
Generating Visual Dynamics from Sound and Context -
Adversarially-Contrastive Optimal Transport -
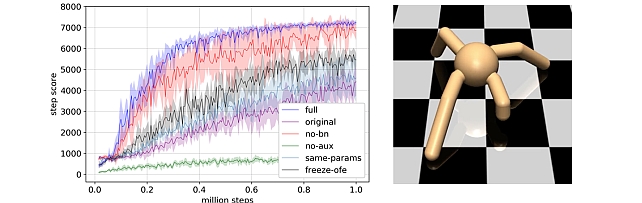
Online Feature Extractor Network -
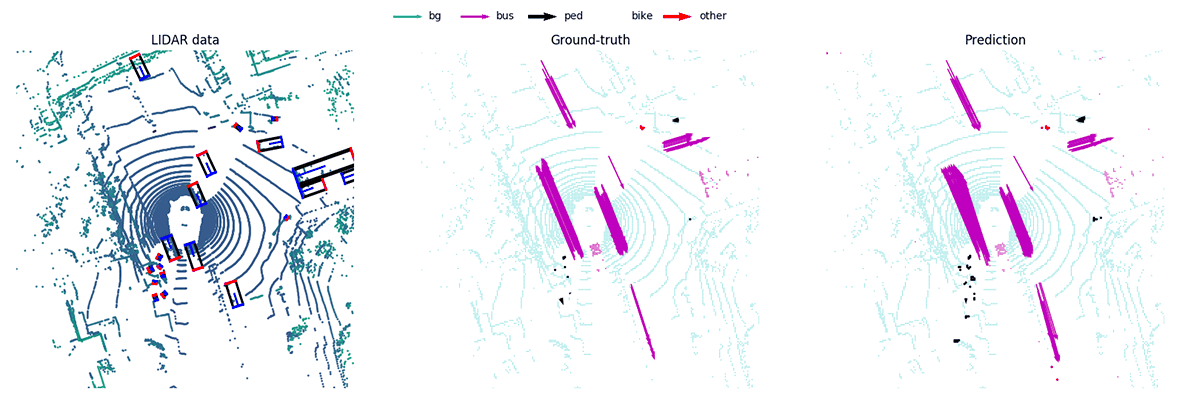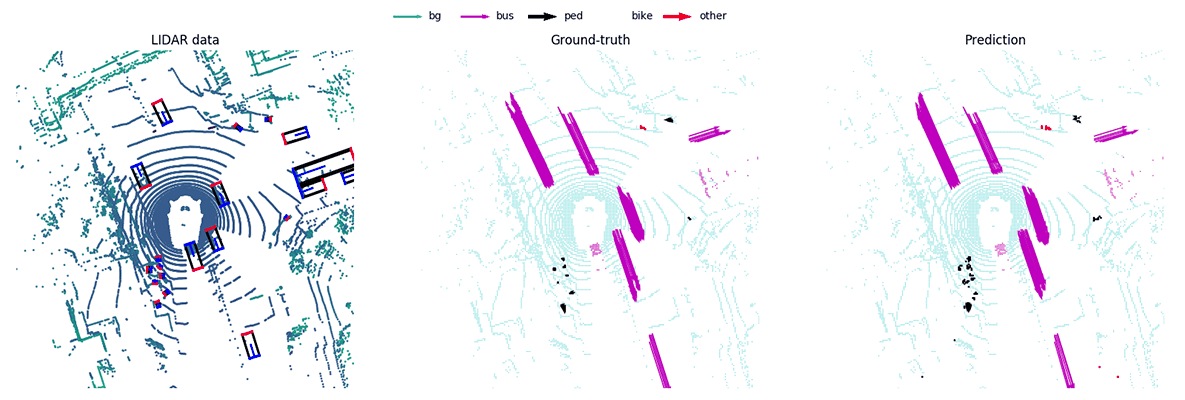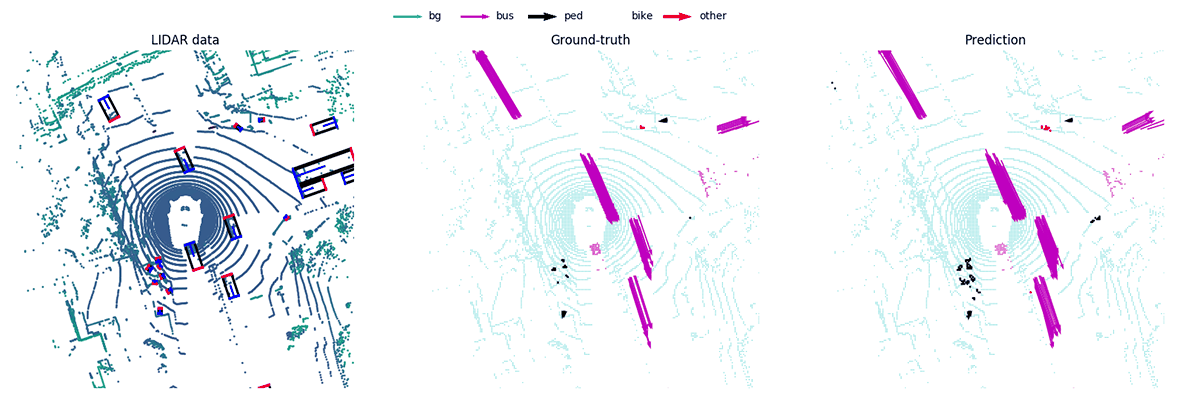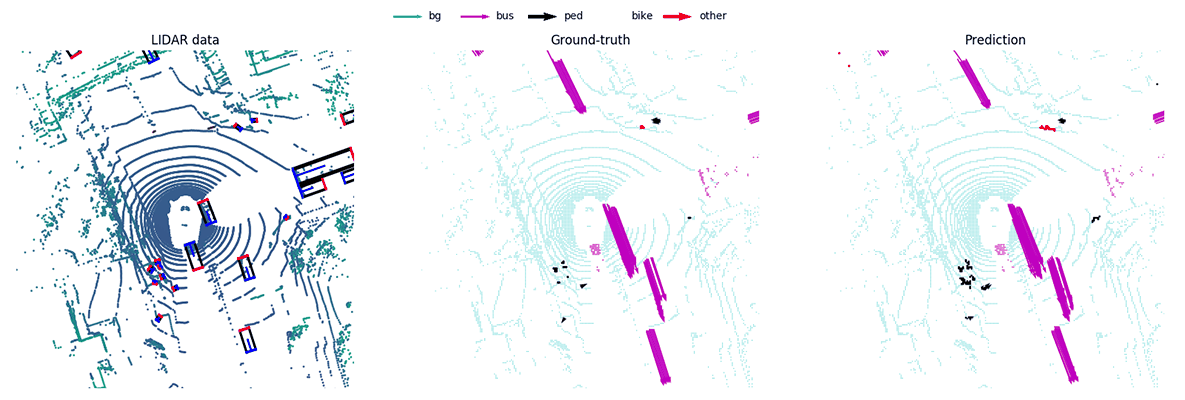
MotionNet -
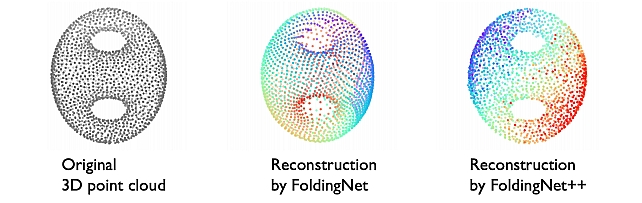
FoldingNet++ -
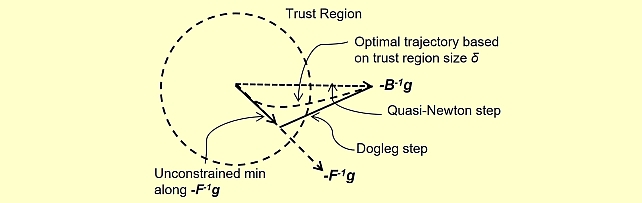
Quasi-Newton Trust Region Policy Optimization -
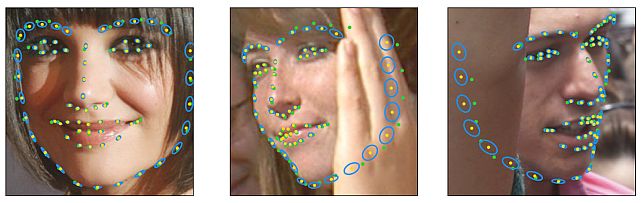
Landmarks’ Location, Uncertainty, and Visibility Likelihood -
Robust Iterative Data Estimation -
Gradient-based Nikaido-Isoda -
Discriminative Subspace Pooling -
Stochastic Interpolants for Speech Enhancement and Separation
-